Generative AI Trends 2027: 8 Shifts Shaping Business and Software Development
Table of contents
- Key takeaways
- Where Enterprise Generative AI Stands Entering 2027
- 8 Generative AI Trends Shaping 2027
- 1. AI agents move from demonstrations to controlled business workflows
- 2. RAG evolves into broader context engineering
- 3. Multimodal AI makes new interfaces practical
- 4. Smaller models and flexible deployment reshape AI architecture
- 5. On-device and hybrid AI expand mobile use cases
- 6. Coding agents change how software is built and reviewed
- 7. AI economics shift from token costs to completed outcomes
- 8. Continuous evaluation and security become essential to production AI
- How Generative AI Technologies Work Together in Enterprise Applications
- Which Generative AI Trends Should Businesses Prioritize?
- From AI Pilot to Production: A Practical Approach
- Conclusion: What Will Separate Successful AI Applications in 2027
- Frequently Asked Questions About Generative AI Trends
- What is the difference between generative AI and agentic AI?
- What is the difference between RAG and context engineering?
- Can businesses use generative AI without sending sensitive data to external AI providers?
- How can businesses measure the ROI of generative AI?
An AI assistant can draft a customer response in seconds. But when that same assistant needs to retrieve an order, check the latest return policy, and determine whether a refund requires approval, the task becomes considerably more complex. It needs access to reliable business data, integration with existing systems, and clear boundaries around the actions it can perform. These practical challenges are becoming increasingly important as companies move beyond AI experiments and integrate generative AI into everyday operations.
This shift is influencing the generative AI trends expected to shape 2027. The eight generative AI trends covered in this article are AI agents moving into controlled business workflows, retrieval-augmented generation (RAG) evolving into context engineering, multimodal interfaces, smaller task-specific models with flexible deployment, on-device and hybrid AI for mobile applications, coding agents, a shift in AI economics toward the cost of completed tasks, and continuous evaluation and security for production AI. Choosing between these technologies involves more than comparing model capabilities, so for each one we’ll examine where it can make a practical difference and what businesses should consider when bringing it into production.
Key takeaways
- AI agents are moving into business workflows, but their reliability depends on well-defined responsibilities, controlled access to enterprise systems, and appropriate human oversight.
- Context engineering is becoming as important as model selection. Giving AI access to accurate, relevant, and authorized information can be more valuable than simply using a larger model.
- Multimodal AI is making new interfaces practical. Applications can interpret images and audio alongside text, although real-time voice features still depend on response time and recognition accuracy.
- AI coding agents are changing software development workflows. They can handle increasingly complex engineering tasks, while the team remains responsible for architecture, code review, testing, and production quality.
- Smaller, task-specific models are taking on routine workloads. Matching each task to an appropriately sized model helps control latency and cost, while data residency requirements increasingly shape where those models can run.
- On-device and hybrid AI are expanding mobile use cases. Local processing supports offline features and keeps some data on the device, but differences in hardware mean many applications will combine on-device and cloud inference.
- The economics of AI applications are receiving greater scrutiny. Businesses need to evaluate the cost of completing real tasks, including failed attempts, infrastructure, and human involvement, rather than relying on model pricing alone.
- Continuous evaluation and security are becoming part of everyday AI operations. Production applications need ongoing testing against real tasks and protection against risks such as prompt injection, which conventional software testing does not fully address.
Where Enterprise Generative AI Stands Entering 2027
AI adoption has become widespread, but turning it into measurable business value remains a challenge. According to the Stanford AI Index Report 2026, 88% of surveyed organizations used AI in at least one business function in 2025, while 70% reported using generative AI. These figures show how widely the technology has entered business operations, although using AI in a particular function doesn't necessarily mean it has fundamentally changed how an organization works.
The difference between adoption and tangible results is also evident in McKinsey's August 2026 State of AI survey. While 44% of respondents reported scaling AI across their enterprises, up from 38% the previous year, only 37% reported a positive contribution to earnings before interest and taxes (EBIT), with little change year over year. Deloitte's State of AI in the Enterprise 2026 paints a similar picture: just 34% of surveyed organizations had begun using AI to substantially transform their businesses through new products, redesigned processes, or changes to their business models.
Although these studies examine AI more broadly than generative AI alone and measure different aspects of adoption, they point to a common challenge for businesses entering 2027. Experimenting with AI or introducing it into existing processes is one thing; demonstrating meaningful improvements in efficiency, quality, or financial performance is another. This distinction provides important context for the eight generative AI trends in this article, particularly as companies look for technologies that can deliver practical value beyond initial experimentation.
8 Generative AI Trends Shaping 2027
1. AI agents move from demonstrations to controlled business workflows
AI agents are becoming capable of handling tasks that involve several steps, external data sources, and interactions with business software. Instead of simply generating a response, an agent can retrieve information, select appropriate tools, and carry out parts of a workflow with limited human involvement. In procurement, an agent could compare supplier quotations, check purchasing requirements, and prepare an order for approval. Deciding whether that order can be placed, however, requires more than the agent's own interpretation of company policy.
In production, agents should access business applications through defined APIs, with authorization rules enforced independently of the model. The system also needs to track completed actions, handle interruptions, and recover from failed operations without accidentally repeating transactions. Human approval remains necessary for decisions involving significant financial commitments, sensitive information, or other consequences that cannot easily be reversed.
The gap between interest in AI agents and readiness to manage them is already evident. According to Deloitte's 2026 State of AI in the Enterprise research, 74% of surveyed leaders expect their organizations to use AI agents at least moderately by 2027, yet only 21% report having mature agent governance in place. Meanwhile, Gartner predicts that more than 40% of agentic AI projects will be canceled by the end of 2027 because of escalating costs, unclear business value, or inadequate risk controls. Although this is a forecast rather than an observed outcome, it highlights the difficulties businesses may face as they move from prototypes to operational systems.
Where multi-agent systems fit
Some workflows benefit from distributing responsibilities across multiple specialized agents. A research application, for instance, might use separate agents to gather information, analyze findings, and verify conclusions. These components can work independently or in parallel, potentially improving how complex tasks are handled.
Multi-agent architectures also introduce coordination overhead, additional model calls, longer execution times, and more opportunities for failure. A single agent working within a structured workflow may be sufficient for many business processes, particularly when the sequence of operations is predictable. Our guide to multi-agent orchestration explores these architectural differences and the situations in which coordinating several agents can be worthwhile.
2. RAG evolves into broader context engineering
Enterprise AI applications frequently need information that a language model cannot obtain from its training data alone. Company policies change, contracts are updated, inventory fluctuates, and customer records contain details that general-purpose models have never encountered. Retrieval-augmented generation (RAG) addresses this problem by supplying relevant information from external sources when the model processes a request, allowing it to generate answers grounded in current business data.
Building a reliable retrieval system involves considerably more than storing documents in a vector database. Keyword and semantic search can be combined to identify relevant content, while metadata filters and reranking help narrow the results. Permissions also matter: a knowledge assistant should retrieve only documents the requesting user is authorized to access. Source attribution makes the resulting answers easier to verify, particularly when employees rely on the application to interpret technical specifications, policies, or contractual information.
As AI applications take on more complex tasks, document retrieval is becoming one part of a broader discipline known as context engineering. Context engineering is the practice of assembling the information a model needs at each step of a task, which can include conversation history, previous tool results, workflow status, or information about the user’s role in addition to retrieved documents. The challenge is to provide the right context without overwhelming the model with irrelevant material.
The growth of context engineering also clarifies the distinction between RAG and fine-tuning. Retrieval is generally better suited to information that changes frequently or requires access controls, whereas fine-tuning can help improve task-specific behavior, formatting, or response patterns when simpler approaches prove insufficient. For enterprise knowledge assistants, the quality of the underlying information and the way it is retrieved often deserve attention before model customization.
Emerline encountered these challenges while developing an AI-powered document search service for B2B customers. The solution involved custom data connectors, specialized document parsing, content chunking, and integration with language models through Azure. The project demonstrates how much of an enterprise AI application's usefulness depends on the systems responsible for preparing and delivering information. Effective data management provides the foundation for keeping that information accessible, consistent, and suitable for retrieval.
3. Multimodal AI makes new interfaces practical
Generative AI applications are becoming less dependent on text-based interactions. Multimodal models can work with combinations of text, images, audio, and video, allowing software to interpret information in forms that are more convenient for users.
In insurance, multimodal AI can help specialists review claims containing photographs, scanned documents, and written descriptions without manually transferring every detail into a separate system. A retail application could combine an uploaded product image with natural-language preferences to improve search results. In both cases, the advantage comes from letting people work with information in a familiar format rather than adapting their tasks to a text-only interface.
Real-time voice applications
Voice introduces its own engineering challenges, particularly when users expect quick, uninterrupted conversations. One approach is to connect speech recognition, a language model, and text-to-speech services in a modular pipeline. Another is to use a multimodal model that can process and generate audio more directly. The modular approach provides greater control over individual components and intermediate results, while integrated audio models can support more fluid interactions.
Neither a modular voice pipeline nor an integrated audio model eliminates the need to handle background noise, interruptions, incomplete requests, or conversational turn-taking. For customer-facing voice applications, end-to-end response time and recognition accuracy can have as much influence on usability as the quality of the generated answer.
Multimodal capabilities are also relevant to visual content creation, product design, and augmented reality applications, where generated assets or conversational features can complement existing visual experiences. Still, generative AI is not a prerequisite for every immersive feature. Product visualization, object tracking, and virtual try-on experiences may be better served by established computer vision and 3D rendering technologies, depending on what the application needs to accomplish.
4. Smaller models and flexible deployment reshape AI architecture
Smaller, task-specific AI models are changing how development teams approach application architecture. Complex reasoning tasks may still justify a powerful general-purpose model, while simpler operations such as classifying support requests, extracting structured information, or producing short summaries can often be handled by smaller, specialized alternatives. Using different models for different workloads can help businesses balance response quality, latency, and infrastructure requirements.
Gartner predicts that by 2027, small, task-specific AI models will see at least three times the usage volume of general-purpose LLMs. In practice, choosing a model involves more than comparing its size or reasoning capabilities. The nature of the task, expected output quality, response time, available infrastructure, and data restrictions all influence the decision.
The following examples illustrate how different workloads and deployment requirements can affect model selection:
|
Workload or requirement |
Model approach |
Main consideration |
|
Intent classification |
Small model or deterministic classifier |
Accuracy and latency |
|
Short summaries |
Lightweight language model |
Quality and cost |
|
Complex analysis |
Advanced reasoning model |
Reliability and context |
|
Regulated or sensitive workloads |
Regional cloud or self-hosted model |
Residency, access, compliance |
|
Offline mobile assistance |
Compatible on-device model |
Hardware limitations |
When an application relies on several models, developers can assign specific tasks to each one or introduce model routing to select an appropriate model for individual requests. Fixed assignments are often easier to maintain when workloads are predictable, whereas dynamic routing can provide greater flexibility at the cost of additional orchestration and testing.
Sovereign AI adds another architectural consideration. The term describes an approach in which a business controls where its AI models run, where data is processed and stored, and which providers are permitted to handle it. For regulated enterprises, that control needs to extend to everything the application processes, including prompts, retrieved information, outputs, and logs.
Regional cloud deployments and self-hosted open-weight models offer different levels of control over data and infrastructure, but neither guarantees compliance on its own. Businesses still need to evaluate provider access, data residency requirements, and the operational responsibilities associated with each option. These considerations are becoming an integral part of AI architecture as organizations combine models with different capabilities and deployment characteristics.
5. On-device and hybrid AI expand mobile use cases
Mobile applications are gaining access to generative AI capabilities that can operate directly on supported devices, reducing their dependence on cloud-based inference. Apple's Foundation Models framework gives developers access to on-device language models, while Google's ML Kit GenAI APIs expose supported Gemini Nano capabilities on compatible Android devices. Depending on the platform and hardware, these technologies can support tasks such as summarization, text rewriting, and structured content generation.
Local processing can be particularly useful when an application handles sensitive information or needs to function with limited connectivity. Certain features can continue working offline, and data processed entirely on the device does not need to be transmitted to a remote inference service. Applications can also avoid cloud inference charges for those requests, although local execution still consumes device resources.
Hardware limitations remain a significant consideration. Available models and supported features differ across devices and operating systems, while memory, processing power, battery consumption, and thermal constraints affect what can run locally. On-device models may also lack the capabilities or context required for more complex enterprise tasks.
Combining on-device and cloud inference
Hybrid architectures allow applications to distribute AI tasks between local and remote models. A field-service application, for example, could summarize a technician's notes on the device while relying on a cloud model to analyze complex equipment issues using centrally stored maintenance records. This gives development teams more flexibility in balancing connectivity, processing requirements, and access to enterprise information.
Implementing such an approach requires clear rules for selecting the appropriate processing environment and handling requests that cannot be completed locally. Device fragmentation makes this especially relevant for cross-platform mobile applications, where the experience needs to remain consistent even when underlying AI capabilities differ.
Emerline has worked with related technical constraints while developing an AI-powered medical surgery recording app. The project used Core ML-compatible neural networks for on-device audio recognition and object segmentation. Although it relied on conventional machine learning rather than generative AI, it illustrates the practical considerations involved in bringing AI processing to mobile devices, including model compatibility and limited computing resources.
6. Coding agents change how software is built and reviewed
AI-powered development tools are expanding beyond code suggestions and autocomplete. Coding agents can explore repositories, modify files, execute development tools, generate tests, and complete defined engineering tasks. These capabilities are beginning to influence not only how development teams work but also which software products businesses decide to build internally.
According to McKinsey's 2026 State of AI survey, 32% of respondents said their organizations had decided against purchasing at least one software product or feature because agentic coding tools made internal development a viable alternative. This suggests that coding agents are beginning to affect build-versus-buy decisions, although the initial speed of implementation does not necessarily translate into lower costs over a product's entire lifecycle. Internally developed software still needs maintenance, security updates, integration work, and long-term technical ownership.
As coding agents take on more implementation work, developers spend more time defining requirements, reviewing architecture, and validating changes. Generated code may appear functional while containing subtle defects, unnecessary dependencies, or assumptions that conflict with the surrounding system. Development teams therefore need acceptance criteria and review practices that are independent of the code-generation process.
The same considerations apply to low-code and no-code development, where AI-assisted tools can make it easier to assemble applications and automate business processes. Faster creation does not remove the need to manage integrations, access permissions, and changes to production systems.
Software testing is evolving alongside implementation. Generative AI can assist with automated software testing by producing test cases, examining coverage, and helping investigate failures. However, tests generated from the same assumptions as the implementation may overlook the same problems. Independent requirements, representative test data, and human review remain important, particularly for complex or business-critical software.
For engineering organizations, the meaningful productivity gains will come from delivering accepted, maintainable software with less effort, rather than simply generating more code. That makes defect rates, rework, review time, and overall delivery performance more useful measures of AI-assisted development than the number of completed prompts or generated lines.
7. AI economics shift from token costs to completed outcomes
The cost of a generative AI application depends on much more than the price of individual model requests. Production systems also incur expenses for data retrieval, infrastructure, integrations, monitoring, failed operations, and human intervention. These costs become particularly important in agentic workflows, where completing a single user request may require several model calls and interactions with external services.
Comparing models solely by token pricing can therefore produce misleading conclusions. A less expensive model may require additional attempts to complete a task or generate results that need extensive correction. A more capable model may have a higher price per request but lower overall costs if it completes the same work successfully with fewer attempts.
Measuring cost per successful task
One way to evaluate these differences is to calculate the cost per successful task: the total operating cost of a workflow divided by the number of tasks it completes successfully. The total should cover every operating expense associated with the workflow, from model calls to human review:
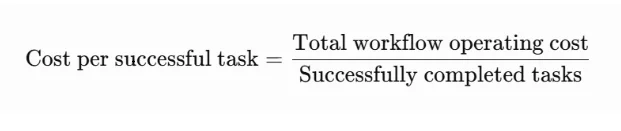
For a document-processing application, the relevant measure could be the cost of producing a correctly extracted and validated document, including any necessary corrections. In customer support, businesses can examine cost per resolved inquiry alongside resolution rates, escalation frequency, and handling time.
Development teams have several options for improving efficiency. Frequently reused information can be cached when freshness requirements permit, while non-urgent workloads may be processed in batches. Reducing unnecessary context can lower inference expenses, and setting limits on agent iterations or tool calls can prevent individual workflows from consuming excessive resources. Each decision involves trade-offs: outdated cached information can produce incorrect results, while aggressive context reduction may leave a model without details it needs.
Operating expenses are already influencing adoption decisions. McKinsey's 2026 survey found that approximately 20% of respondents considered AI-related operating costs, including token costs, a constraint on their organization's use of AI. For businesses planning larger deployments, understanding workflow-level economics is increasingly important when estimating whether an application can deliver value at the expected volume of use.
8. Continuous evaluation and security become essential to production AI
Traditional software testing alone is not sufficient for applications that depend on generative AI. Model outputs can vary between requests, retrieved information may be incomplete, and changes to underlying models can affect previously reliable behavior. As AI becomes part of operational software, evaluation needs to reflect the specific tasks an application performs and the consequences of getting them wrong.
Different applications require different measurements. A knowledge assistant can be evaluated for retrieval relevance, factual support, answer completeness, and compliance with document-access permissions. An AI agent also needs to be assessed on tool selection, action accuracy, workflow completion, and recovery from failures. Deterministic tests remain appropriate for business rules and structured requirements, while model-based evaluators can help assess more subjective output qualities when calibrated against human-reviewed examples.
Evaluation also becomes an ongoing activity rather than a one-time check before launch. Teams need representative test datasets, monitoring of production behavior, and a way to investigate failures or compare performance after model and application updates.
Security risks extend beyond model responses
AI applications introduce security concerns that conventional input validation and software testing do not fully address. The OWASP Top 10 for LLM Applications identifies threats such as prompt injection, sensitive information disclosure, and excessive agency. For instance, a document retrieved by an AI assistant could contain malicious instructions designed to influence the model's behavior. If the application treats those instructions as trusted commands, an attacker may be able to manipulate subsequent actions.
Protecting against these scenarios requires a clear separation between information the model can read and instructions the application is authorized to execute. Access permissions, sensitive operations, and business rules should be enforced by the surrounding software rather than entrusted to the model's judgment. Execution traces and audit logs also help organizations understand what actions were taken, which systems were involved, and how incidents occurred.
Beyond application-level security, enterprise AI deployments must account for data retention, encryption, privacy obligations, and the management of model and infrastructure changes. The NIST Generative AI Profile offers a framework for identifying and managing risks associated with generative AI. Continuous evaluation and security controls make it possible to assess AI systems against the requirements of their actual operating environments, where the consequences of an incorrect answer can be very different from those of an unauthorized transaction.
How Generative AI Technologies Work Together in Enterprise Applications
An enterprise AI application may appear to handle a single request, but several components can be involved in producing the result. In the hybrid architecture shown in Figure 1, supported tasks can run locally on a user’s device, while requests requiring cloud-based processing pass through an orchestration layer. This layer selects an appropriate AI model, retrieves information from enterprise knowledge sources when necessary, and communicates with business systems through controlled tools and APIs. Each component has a distinct role, allowing the application to combine AI capabilities with existing data and operational processes.
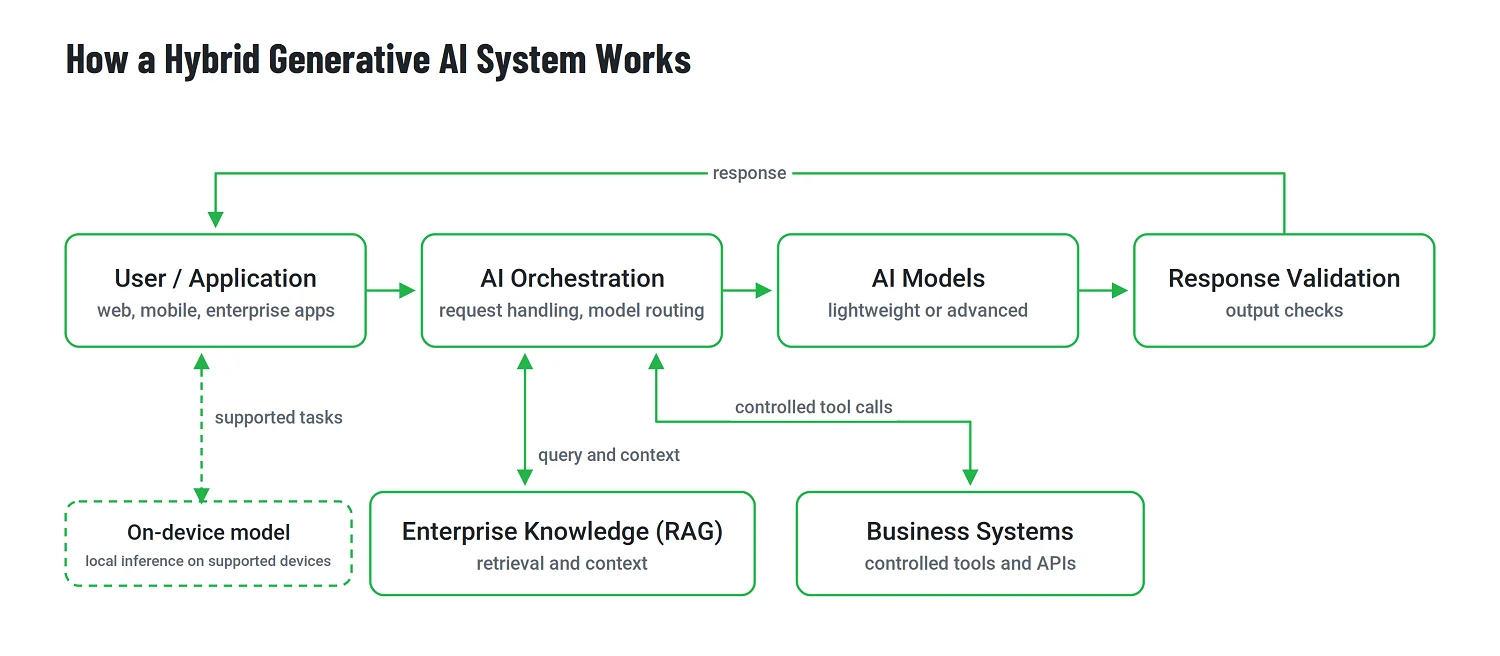
For requests handled through the cloud orchestration path, generated outputs pass through application-level validation before being returned to the user. Authorization for protected operations remains the responsibility of the connected business systems, while monitoring and evaluation help teams understand how the application behaves in practice. The diagram shows the main processing paths rather than every infrastructure component, providing a simplified view of how these technologies can operate within a single enterprise application.
Which Generative AI Trends Should Businesses Prioritize?
Not every generative AI trend deserves the same level of attention from every business. The requirements of a manufacturing company looking to improve access to maintenance documentation differ from those of a retailer developing visual product search or a SaaS provider introducing automated workflows. The technologies may overlap, but their relevance depends on the problems a company is trying to solve, the systems it already uses, and the results it expects to achieve.
Some applications, such as RAG-based knowledge assistants and AI-assisted coding, already have established implementation approaches. Others, particularly autonomous multi-agent workflows, involve greater operational uncertainty. The following table shows where different generative AI technologies can be useful and which factors deserve attention when evaluating them.
|
Business need |
Relevant GenAI trend |
What to consider |
|
Employees spend too much time searching internal documents or technical records |
RAG and context engineering |
Data quality, retrieval accuracy, and access permissions |
|
Customer support or administrative processes involve repetitive, multistep tasks |
AI agents and workflow automation |
Process complexity, integration requirements, and the consequences of incorrect actions |
|
Retail or customer-facing applications need more intuitive ways to interact with products and services |
Multimodal AI |
User experience, response latency, and accuracy of image or voice processing |
|
Mobile employees need AI assistance in environments with limited connectivity |
On-device and hybrid AI |
Device compatibility, local processing capabilities, and cloud availability |
|
Software development teams want to accelerate implementation and testing |
Coding agents and AI-assisted development |
Code quality, review effort, maintainability, and actual delivery improvements |
|
AI-powered applications handle large request volumes or increasingly complex workloads |
Specialized models and inference optimization |
Output quality, infrastructure requirements, and cost per successful task |
These examples also show why technology maturity alone is not enough to determine whether a solution is suitable. An internal knowledge assistant that retrieves company policies presents very different operational risks from an agent that can approve payments or modify customer accounts. Even when both applications use established AI technologies, the amount of testing, oversight, and integration work they require will differ considerably.
For businesses planning generative AI investments in 2027, the more useful question is which capabilities can address an existing operational need with a reasonable level of effort and risk. That assessment provides a stronger basis for deciding where to invest than the popularity or technical sophistication of a particular AI trend.
From AI Pilot to Production: A Practical Approach
Once a business identifies a promising generative AI use case, the next challenge is to determine whether it can work effectively under real operating conditions. A successful demonstration is a useful starting point, but production deployment requires a clear understanding of the existing workflow, available data, integration requirements, and expected results. The following five steps can help teams move from an initial concept to an application ready for everyday use.
- Define the workflow and establish a baseline. Identify the process you want to improve and document how it currently works, including delays, recurring errors, and tasks that require manual effort. Establish measurable targets for processing time, accuracy, costs, or other relevant outcomes so the pilot can be compared with the existing approach.
- Assess data and integration readiness. Determine which information the application needs, where it is stored, and how it can be accessed. Incomplete records, inconsistent data, or unavailable APIs can undermine an otherwise promising solution, so these issues should be addressed before committing to a more complex implementation.
- Build a focused pilot. Select an architecture appropriate for the task and test it with representative business scenarios rather than idealized examples. The initial scope should be manageable while still covering the integrations, user interactions, and exceptions that are likely to influence performance.
- Evaluate the complete workflow. Assess the pilot against the criteria established at the beginning, including task accuracy, completion rates, human review effort, and operating costs. Testing should also cover different permission levels, unexpected inputs, and system failures to reveal problems that may not appear during routine demonstrations.
- Prepare for production and ongoing maintenance. Before expanding deployment, confirm that the application can handle expected workloads and that monitoring, recovery procedures, and security controls are in place. Assign responsibility for maintaining integrations, reviewing performance, and managing changes to models or data sources so the solution remains dependable after launch.
Conclusion: What Will Separate Successful AI Applications in 2027
In 2027, the strongest generative AI applications will combine capable models with reliable data access, controlled execution, and sustainable operating costs. For engineering teams, the priority is to build systems that remain dependable as workloads, integrations, and business requirements change.
At Emerline, we help businesses put these ideas into practice, from identifying promising use cases and integrating AI with existing systems to developing applications ready for production. Explore our generative AI development services to learn how we can help you bring AI capabilities into your software products and business workflows.
Frequently Asked Questions About Generative AI Trends
What is the difference between generative AI and agentic AI?
Generative AI creates content such as text, images, audio, and code in response to user inputs. Agentic AI takes this further by using models to plan and execute tasks, interact with external tools, and work toward specific objectives. An agent may rely on generative AI to interpret information or make decisions, but generating content alone does not make a system agentic.
What is the difference between RAG and context engineering?
RAG is a technique for retrieving relevant information from external sources and supplying it to a language model when it processes a request. Context engineering covers a wider scope: everything the model receives at each step of a task, which may include retrieved documents as well as conversation history, tool results, and the user’s access permissions. In agentic workflows, the way this broader context is assembled often has a greater effect on reliability than retrieval quality alone.
Can businesses use generative AI without sending sensitive data to external AI providers?
Yes. Businesses can use self-hosted models or supported on-device AI capabilities to process sensitive information within their own controlled environments. However, keeping inference local is only part of the solution: applications may still transmit data through integrations, logging systems, or external services. Regional cloud deployments can help organizations meet data residency requirements, but they generally involve an external provider and should be evaluated separately.
How can businesses measure the ROI of generative AI?
Businesses should compare the measurable benefits of an AI application with the full cost of developing, deploying, and maintaining it. Depending on the use case, relevant indicators may include reduced processing time, fewer errors, lower operational expenses, or additional revenue. These benefits should be assessed against a baseline that reflects how the work was performed before AI was introduced, accounting for infrastructure, integrations, model usage, maintenance, and human review.
Updated on Oct 29, 2026